Data Engineering for Smarter Decisions
Your data is only as valuable as the infrastructure that moves and transforms it. InterCode builds reliable data pipelines, warehouses, and streaming architectures that turn raw data into the insights your business depends on.
Turn Raw Data Into Business Value
Most organizations sit on massive amounts of data trapped in silos, spreadsheets, and legacy systems. InterCode's data engineering practice builds the infrastructure that connects these sources, transforms raw data into clean and structured formats, and delivers it to the tools and teams that need it.
We design and implement data pipelines that handle everything from batch ETL jobs running overnight to real-time streaming architectures processing millions of events per second. Our solutions scale horizontally, handle failures gracefully, and include monitoring that alerts your team before data quality issues affect downstream consumers.
Whether you need a modern data warehouse on Snowflake, a data lake on AWS, or a streaming platform on Kafka, InterCode provides the engineering expertise to build data infrastructure that is reliable, performant, and maintainable for the long term.
Related Case Studies
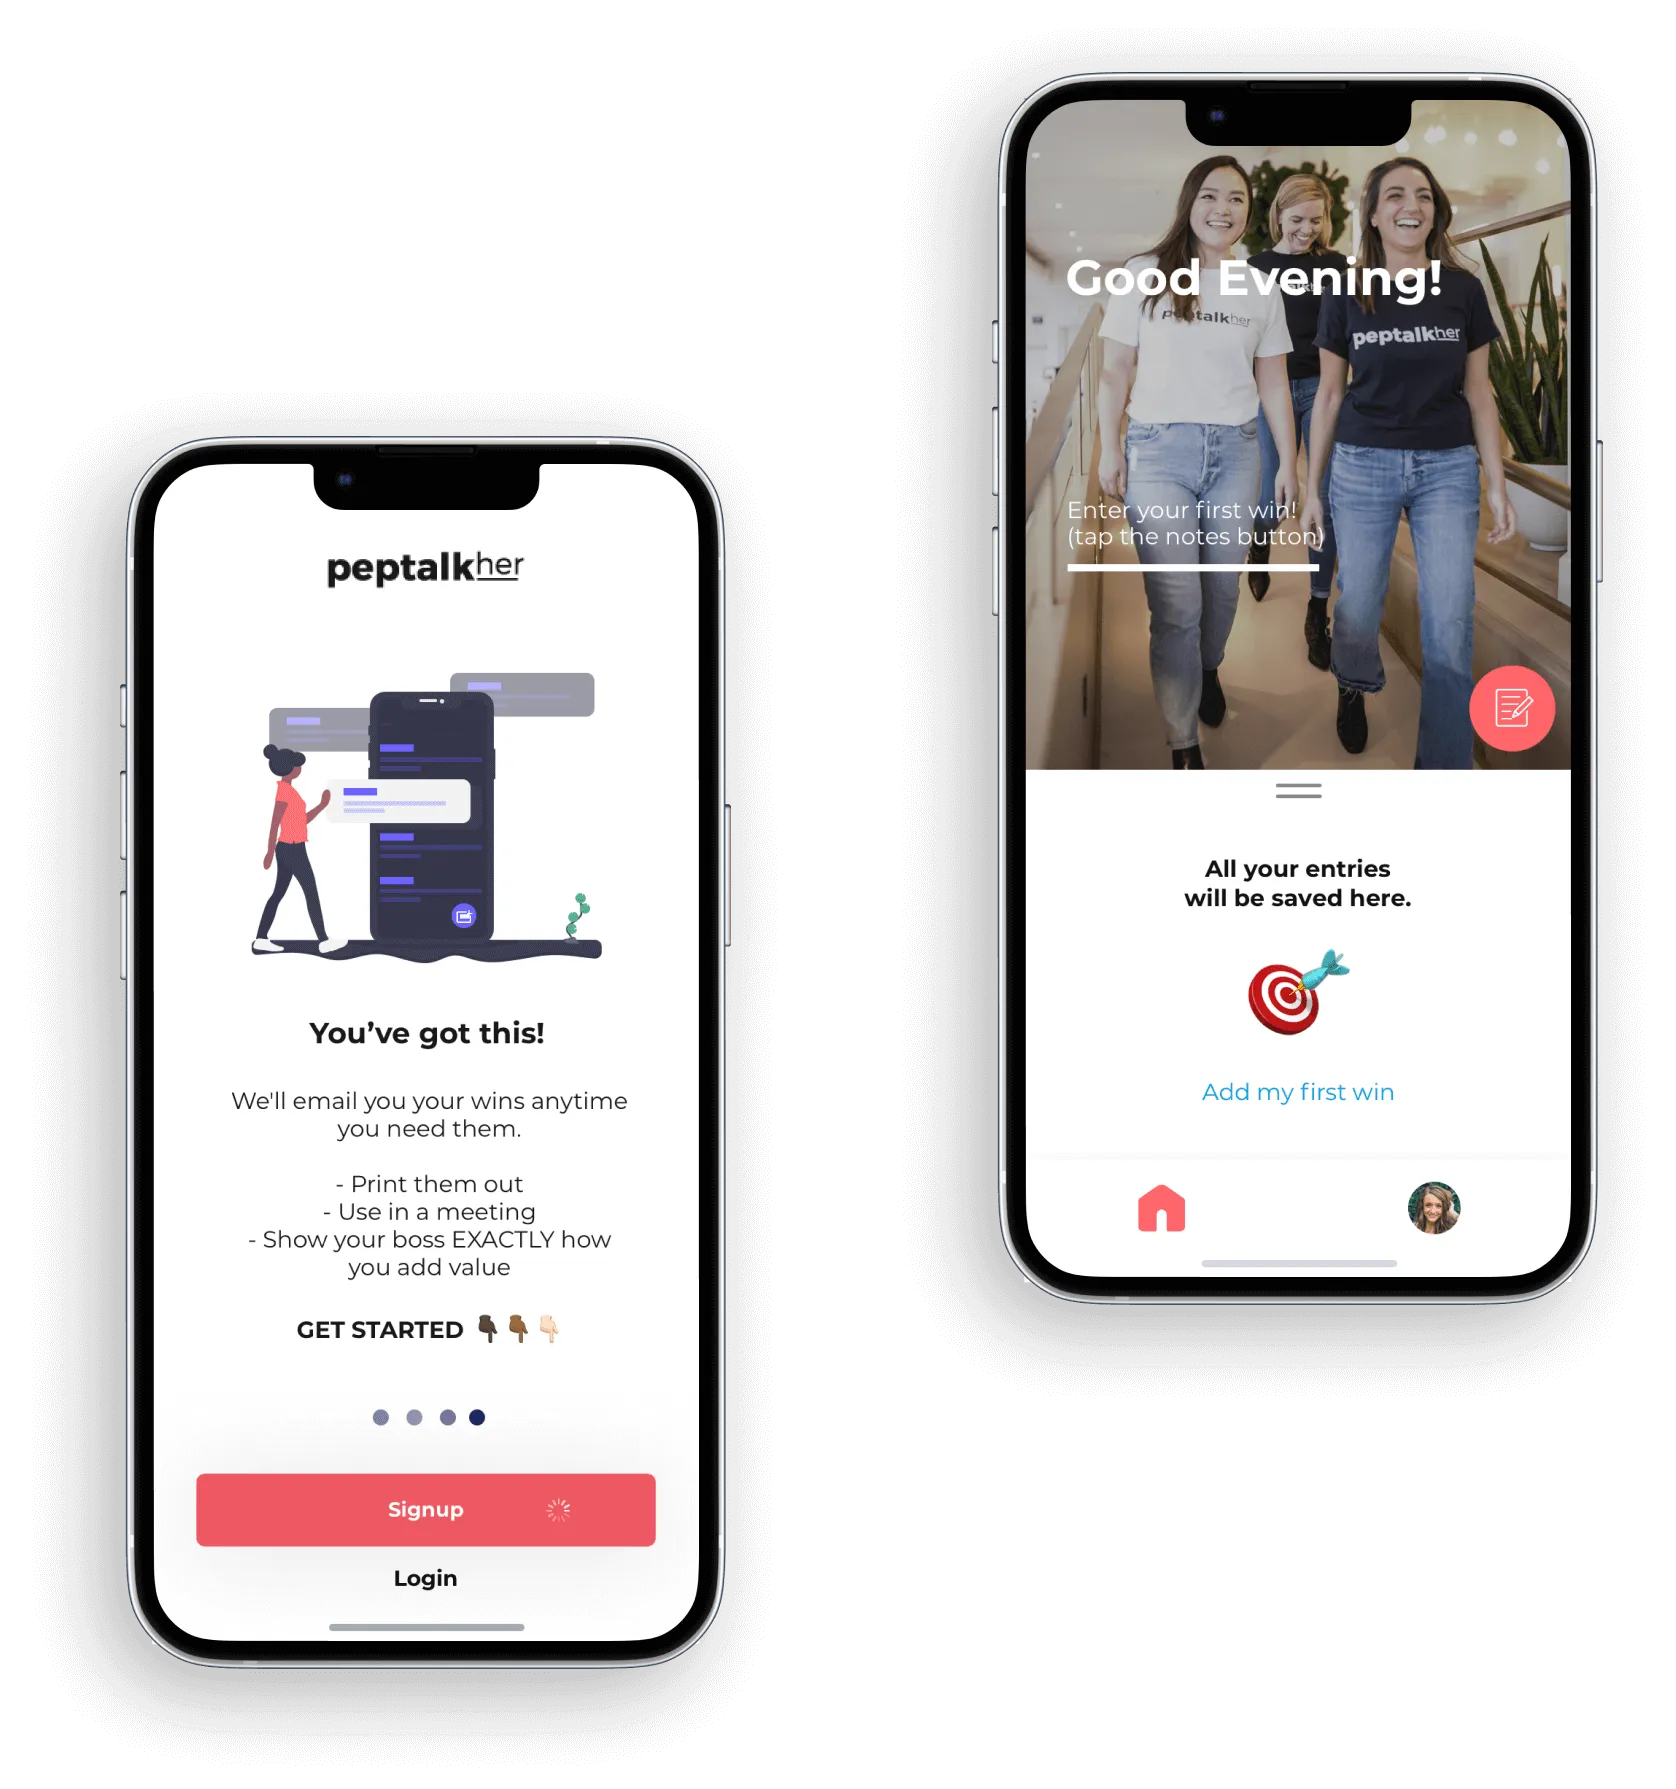
Women's Career Coaching App — PepTalkHer
The Mobile App gives you a career pep talk when you need it most. It helps you track your career successes to coach users in confidence & negotiation skills by creating notes, AKA wins and sharing it with bosses.
Read case study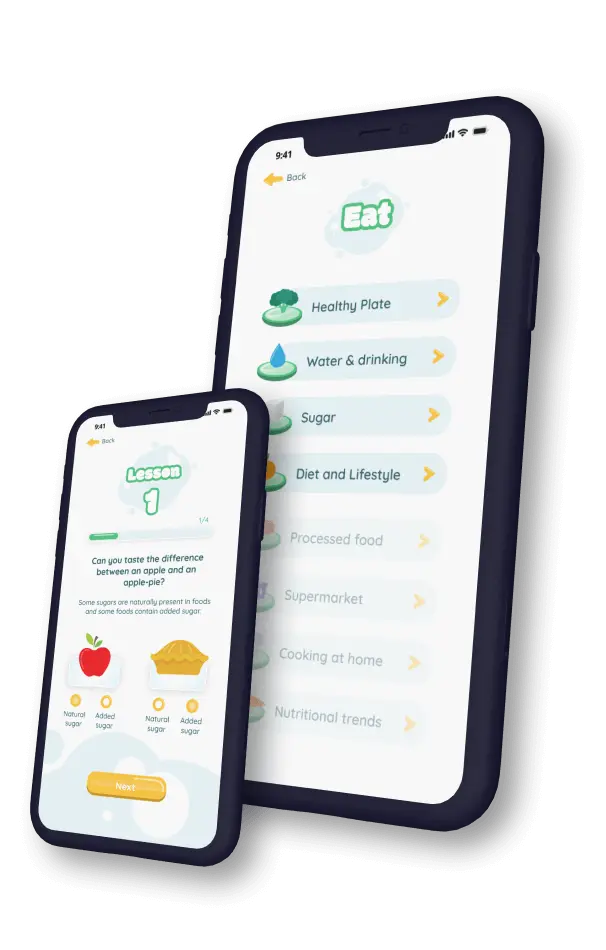
Children's Health & Wellness Mobile App — BeeHealthy
BeeHealthy aims to support Ukrainian refugee children by providing stress management, nutrition education, and exercise activities through an accessible mobile app, aiding in their holistic well-being and resilience.
Read case study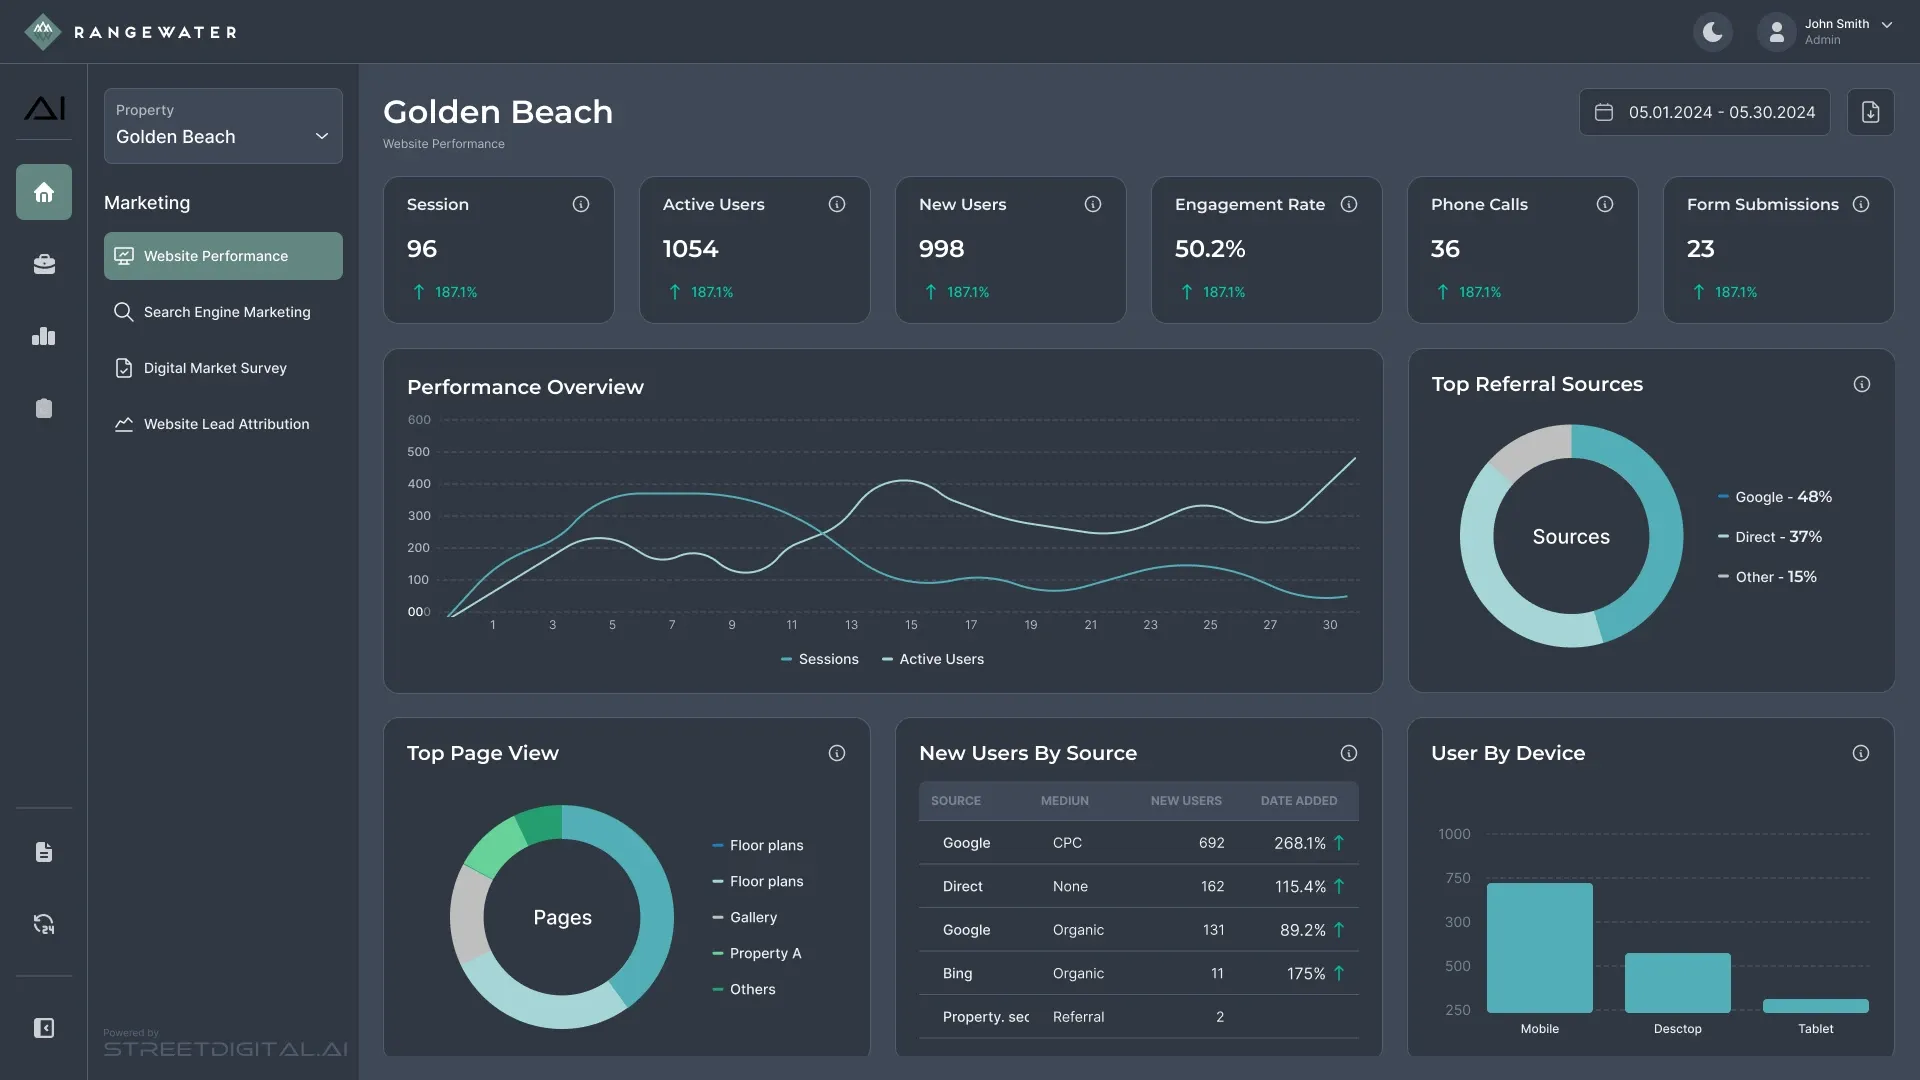
AI-Powered BI Software and Marketing Automation for Street Digital AI client
A luxury apartment marketing agency was losing money and clients to a rigid no-code BI tool. InterCode replaced it with a cloud-native data and analytics platform on Google Cloud Platform — cutting costs by 75%, loading dashboards in under 3 seconds, and onboarding new clients 4x faster. The platform has since evolved into an AI-driven marketing operations system built with Anthropic's Claude. This case study breaks down the challenge, the solution, and the results.
Read case studyWhat We Deliver
End-to-end data engineering from pipeline development to governance.
Data Pipeline Development
Automated ETL/ELT pipelines that move data reliably from source systems to your warehouse or lake.
- Batch and incremental processing
- Schema evolution handling
Data Warehouse Architecture
Modern warehouse design on Snowflake, BigQuery, or Redshift with dimensional modeling for fast analytics.
- Star and snowflake schemas
- Slowly changing dimension handling
Real-Time Streaming
Kafka and Spark Streaming architectures for use cases that demand sub-second data freshness.
- Event-driven architectures
- Exactly-once processing guarantees
Data Quality & Governance
Automated data quality checks, lineage tracking, and access controls that build trust in your data.
- Data validation rules
- Column-level lineage tracking
Data Lake Design
Scalable data lakes with proper partitioning, cataloging, and access patterns for diverse analytical workloads.
- Medallion architecture (bronze/silver/gold)
- Cost-optimized storage tiers
Our Data Engineering Process
Data Landscape Assessment
We map your data sources, existing pipelines, and analytics needs to build a comprehensive data strategy.
- Source system inventory
- Data quality baseline
Architecture Design
Design the target data architecture including storage, processing, and serving layers.
- Technology selection
- Data model design
Pipeline Development
Build and test data pipelines with proper error handling, retry logic, and monitoring.
- Incremental load strategies
- Data validation checks
Warehouse/Lake Setup
Provision and configure your data warehouse or lake with optimized schemas and access controls.
- Performance-tuned schemas
- Role-based access control
Monitoring & Alerting
Set up pipeline monitoring, data quality dashboards, and alerting for failures and anomalies.
- Pipeline health dashboards
- SLA tracking and alerting
Documentation & Handoff
Deliver comprehensive documentation and train your team on pipeline maintenance and extension.
- Data dictionary
- Runbook documentation
Data Engineering Tools We Use
Battle-tested tools for every data engineering challenge.



We select data tools based on your data volume, latency requirements, and team expertise. dbt and Airflow form our default modern data stack, supplemented with Spark or Kafka when scale demands it.
Why InterCode for Data Engineering
Production-Scale Experience
Our data engineers have built pipelines processing billions of records for clients across finance, logistics, and healthcare.
Data Quality Obsessed
Every pipeline includes validation, monitoring, and alerting because bad data is worse than no data.
Modern Data Stack
We use the modern data stack (dbt, Airflow, Snowflake) that is rapidly becoming the industry standard.
Knowledge Transfer Focus
We build your team's data engineering capability alongside the infrastructure, ensuring long-term independence.
From Our Blog
Insights and practical guides from our engineering team
Custom Code vs No-Code vs AІ
Of course, we don’t know what is best for you in your specific case. But we know for sure that the best solution for us is Custom сode.
To hire a freelancer OR a company. What to choose?
Whether you're looking for a freelancer or a company to help with your projects, knowing the difference is key.
PWA + AMP: The Future of Fast, Engaging, and Reliable Web Applications
Learn how combining Progressive Web Apps (PWA) and Accelerated Mobile Pages (AMP) can supercharge your mobile website's speed, engagement, and user experience.
More Data Engineering & Analytics Services
Business Intelligence That Drives Action
Dashboards that sit unused help nobody. InterCode builds business intelligence solutions designed around the questions your team actually asks, delivering insights in formats that drive decisions and surface opportunities before your competitors see them.
Learn moreData Pipelines That Never Let You Down
Fragile pipelines that break silently cost you time, money, and trust. InterCode builds data pipelines with robust error handling, automatic retries, and proactive monitoring so your data arrives on time, every time.
Learn moreFrequently Asked Questions
ETL (Extract, Transform, Load) transforms data before loading it into the warehouse. ELT (Extract, Load, Transform) loads raw data first and transforms it inside the warehouse using tools like dbt. We recommend ELT for most modern use cases because it leverages the warehouse's compute power and keeps raw data available for future transformations.
Snowflake is our default recommendation for its separation of storage and compute, automatic scaling, and ease of use. BigQuery is excellent for GCP-native teams, and Redshift works well for AWS-heavy environments. We help you evaluate based on your cloud provider, budget, and team expertise.
Most analytics use cases work well with batch pipelines running every few minutes to hours. Real-time streaming is necessary for use cases like fraud detection, live dashboards, and event-driven architectures. We assess your latency requirements and recommend the simplest approach that meets your needs.
We implement data quality checks at every stage of the pipeline using tools like dbt tests, Great Expectations, or custom validation rules. Pipeline monitoring alerts your team when data quality issues are detected, and we design circuits breakers that prevent bad data from reaching downstream consumers.
A single-source pipeline with basic transformations can be built in 1-2 weeks. A comprehensive data platform with multiple sources, a warehouse, and analytics layer typically takes 6-12 weeks. We prioritize high-value data sources first and deliver incrementally.
We work with Apache Airflow, dbt, Apache Spark, Kafka, and cloud-native services like AWS Glue, Redshift, BigQuery, and Snowflake. Our tool selection is driven by your data volume, latency requirements, and existing infrastructure. We always prioritize reliability and maintainability.
Yes, we build both batch and real-time streaming pipelines. For real-time use cases, we use technologies like Apache Kafka, AWS Kinesis, and Flink to process events as they occur. This enables use cases like live dashboards, fraud detection, and real-time personalization.
Yes, we build business intelligence solutions ranging from self-service analytics platforms with tools like Looker and Metabase to fully custom dashboards with D3.js or Recharts. We focus on creating visualizations that answer real business questions and drive action, not just display data.
Absolutely. We plan and execute data warehouse migrations, whether you are moving from on-premises databases to cloud warehouses like Snowflake or BigQuery, or consolidating multiple data sources into a unified platform. We ensure data integrity throughout the migration process.
Ready to Unlock Your Data's Potential?
Tell us about your data sources and analytics goals. We will design a data engineering strategy that turns raw data into actionable insights.
Contact Us